
 Script Planner Assistant▸
 AI Apps
 AI News
Seed-ASR: ByteDance's Automatic Speech Recognition Model

Seed-ASR: ByteDance's Automatic Speech Recognition Model
Seed-ASR, an automatic speech recognition model from ByteDance, converts various speech into text information. Unlike traditional TTS models that target a single task, Seed-TTS is capable of modeling a wide range of voices and can be controlled across many dimensions simultaneously. It can recognize different languages, dialects, accents, and even speech imperfections such as swallowed words.Seed-ASR was trained on over 20 million hours of speech data and nearly 900,000 hours of paired ASR data.In addition to Mandarin, it supports 13 Chinese dialects, 7 foreign languages, and English in various accents.
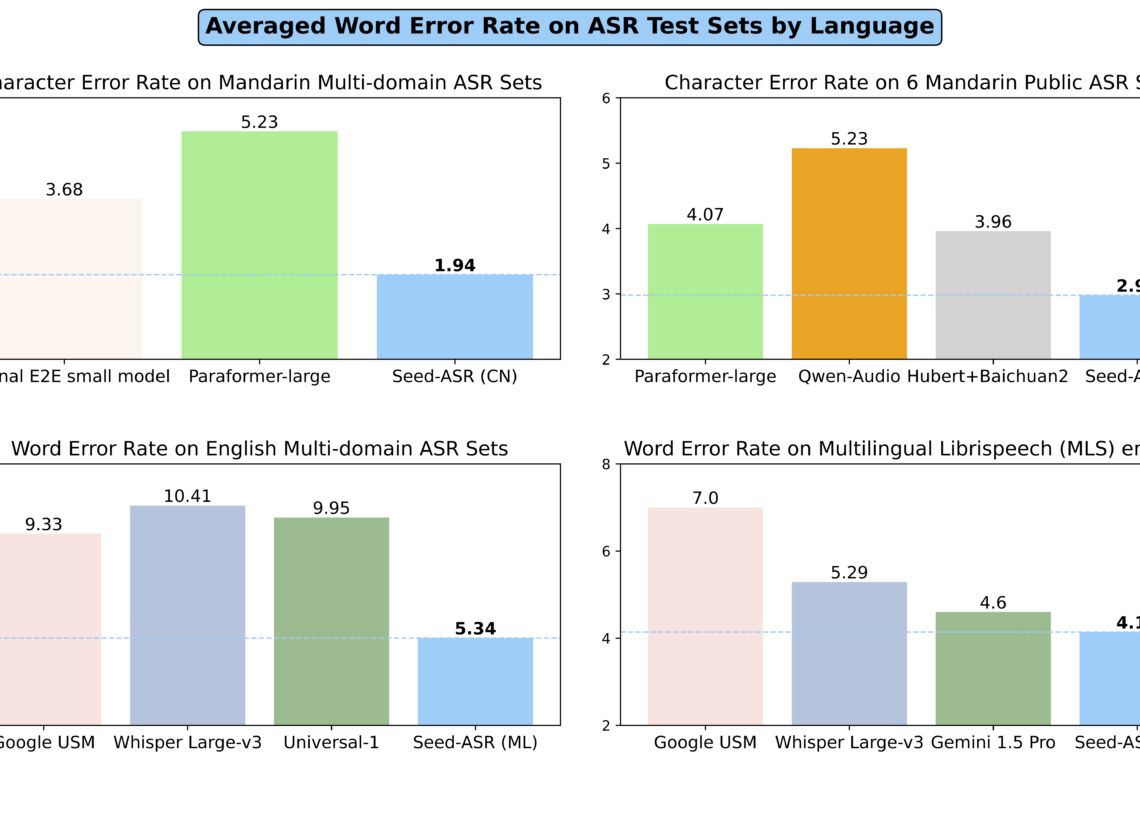
Seed-ASR has powerful context-aware capabilities, enabling it to recognize speech content within a specific context. For example, the model can leverage historical conversations or meeting records to more accurately identify names, places, or other context-related keywords in the current speech.
Seed-ASR offers strong scalability. This means it is not just a fixed system, but a platform that can be customized according to specific needs. For example, if you want it to specialize in recognizing medical terminology or understand a particular accent, this can be achieved through fine-tuning.
The core technology behind Seed-ASR is the integration of large language models into speech recognition, which brings context understanding capabilities to Seed-ASR. This is not simply about combining two systems together; it fundamentally changes the way speech is processed. It's like equipping a speech recognition system with a super brain that can not only listen but also think.
Seed-ASR Technical Highlights:
High-precision Recognition: Processes complex speech input through a model with billions of parameters to achieve high-precision recognition.
Large-capacity Model: The use of a large language model improves the accuracy of speech recognition and the ability to understand context. It's like having a "supercomputer" help you take dictation of notes—just thinking about it feels incredibly cool.
Multilingual Support: Includes Mandarin, 13 Chinese dialects, and multiple foreign languages, with plans to expand to more than 40 languages.
Context Awareness: Capable of incorporating contextual information to improve recognition accuracy, much like when you chat with a friend and it understands what you have previously discussed, then uses that information to more accurately comprehend what you are currently saying.
Staged Training Approach: Includes self-supervised learning, supervised fine-tuning, contextual fine-tuning, and reinforcement learning, progressively enhancing the model's capabilities.
Seed-ASR Application Scenarios:
Human-Computer Interaction: Provides a voice input channel by converting speech to text in real time as input, enabling fast and convenient interaction with devices, hardware, or applications.
Content Moderation: Converts recordings into text and analyzes them using quality inspection rules to promptly identify non-compliant content and take intervention measures.
Meeting and Interview Transcription: Recognizes meeting and interview audio into text in real time or asynchronously, automatically segmenting the speech portions for recognition, reducing costs and increasing efficiency.
Audio and Video Subtitles: Supports automatic recognition and conversion of speech and lyrics in audio and video into text, generating subtitle content corresponding to the audio and video with a single click.
Seed-ASR has already been applied in the Doubao APP, where users have employed it in scenarios such as English conversations, virtual chat companions, and cloning the voices of friends and family. For more enterprise customers, Seed-ASR leverages Volcano Engine and has also been deployed in scenarios such as voice interaction, content moderation, meeting and interview transcription, and audio/video subtitles.
To date, the Doubao large model team's speech direction has released a number of technical achievements, including Seed-TTS and Seed-ASR.
Seed-ASR Official Website:https://bytedancespeech.github.io/seedasr_tech_report/









