
 Script Planner Assistant▸
 AI Apps
 AI News
Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
小编 ·

Hallo: Hierarchical Audio-Driven Visual Synthesis for Portrait Image Animation
Hallo can generate singing and talking videos from a single image and audio input, while also controlling facial expressions and poses. Compared with EMO, Hallo employs a diffusion model to achieve hierarchical audio-driven visual synthesis, enabling it to generate animations with synchronized lip movements, expression changes, and pose variations based on input speech. This improves the alignment accuracy between speech and the generated animations, ensuring that the lips, expressions, and poses in the animation stay in sync with the speech.
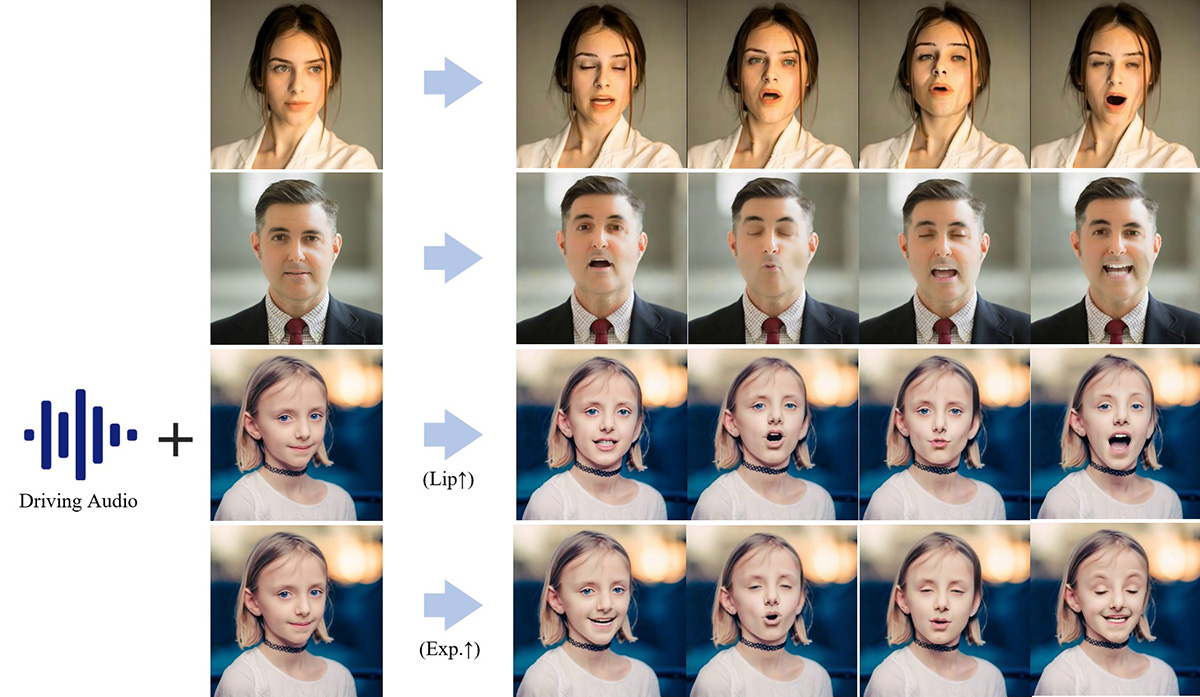
Hallo Key Features:
Virtual Character Animation Generation: Generates realistic and dynamic virtual character animations from speech audio input, achieving precise synchronization of lip movements, expressions, and poses.
Real Character Animation Generation: Applies the technology to audio-driven animation generation for real people, producing animations that accurately reflect changes in their expressions and movements.
Multiple Motion Controls: Provides precise control over facial expressions, poses, and lip movements, supporting adaptive control of various expressions and poses to enhance animation diversity and realism.
Cross-Identity Application: Supports personalized animation generation for different identities, producing animation effects that adapt to different character identities from audio input.
Singing Animation Generation: Generates synchronized singing animations from speech and song audio input, with animations that accurately reflect the lip movements and expression changes during singing.
Other Features of Hallo:
Real-Time Performance: The diffusion model architecture enhances the real-time performance of animation generation, making the generated animations more realistic and natural.
Personalization: Customizable personalized animation effects can be created for different actors or characters.
Diversity: Offers multiple motion controls, including expressions, poses, and lip movements, making animations more diverse and realistic.
Hallo Project Page: https://fudan-generative-vision.github.io/hallo
Hallo GitHub: https://github.com/fudan-generative-vision/hallo
Hallo Paper: https://arxiv.org/abs/2406.08801
HuggingFace: https://huggingface.co/fudan-generative-ai/hallo









