
 Script Planner Assistant▸
 AI Apps
 AI News
Alibaba Cloud Releases Qwen2 Open-Source Model
小编 ·

Alibaba Cloud Releases Qwen2 Open-Source Model
Alibaba Cloud has released the Qwen 2 open-source model, with performance surpassing all current open-source models and domestic closed-source models.
The Qwen 2 models come in multiple sizes, including 0.5B, 1.5B, 7B, 57B-A14B, and 72B versions. In benchmarks of models of the same size, the Qwen 2 models have achieved results that surpass all other open-source models. I tested it on the CompassArena large model arena, and it is indeed very strong — it should be one of the most excellent models in Chinese at present.
Qwen 2 Features:
Pre-trained and instruction-tuned models in 5 sizes, including Qwen2-0.5B, Qwen2-1.5B, Qwen2-7B, Qwen2-57B-A14B, and Qwen2-72B;
Trained on data in 27 languages in addition to English and Chinese;
State-of-the-art performance across a wide range of benchmark evaluations;
Significantly improved coding and mathematics performance;
Qwen2-7B-Instruct and Qwen2-72B-Instruct support extended context lengths of up to 128K tokens.
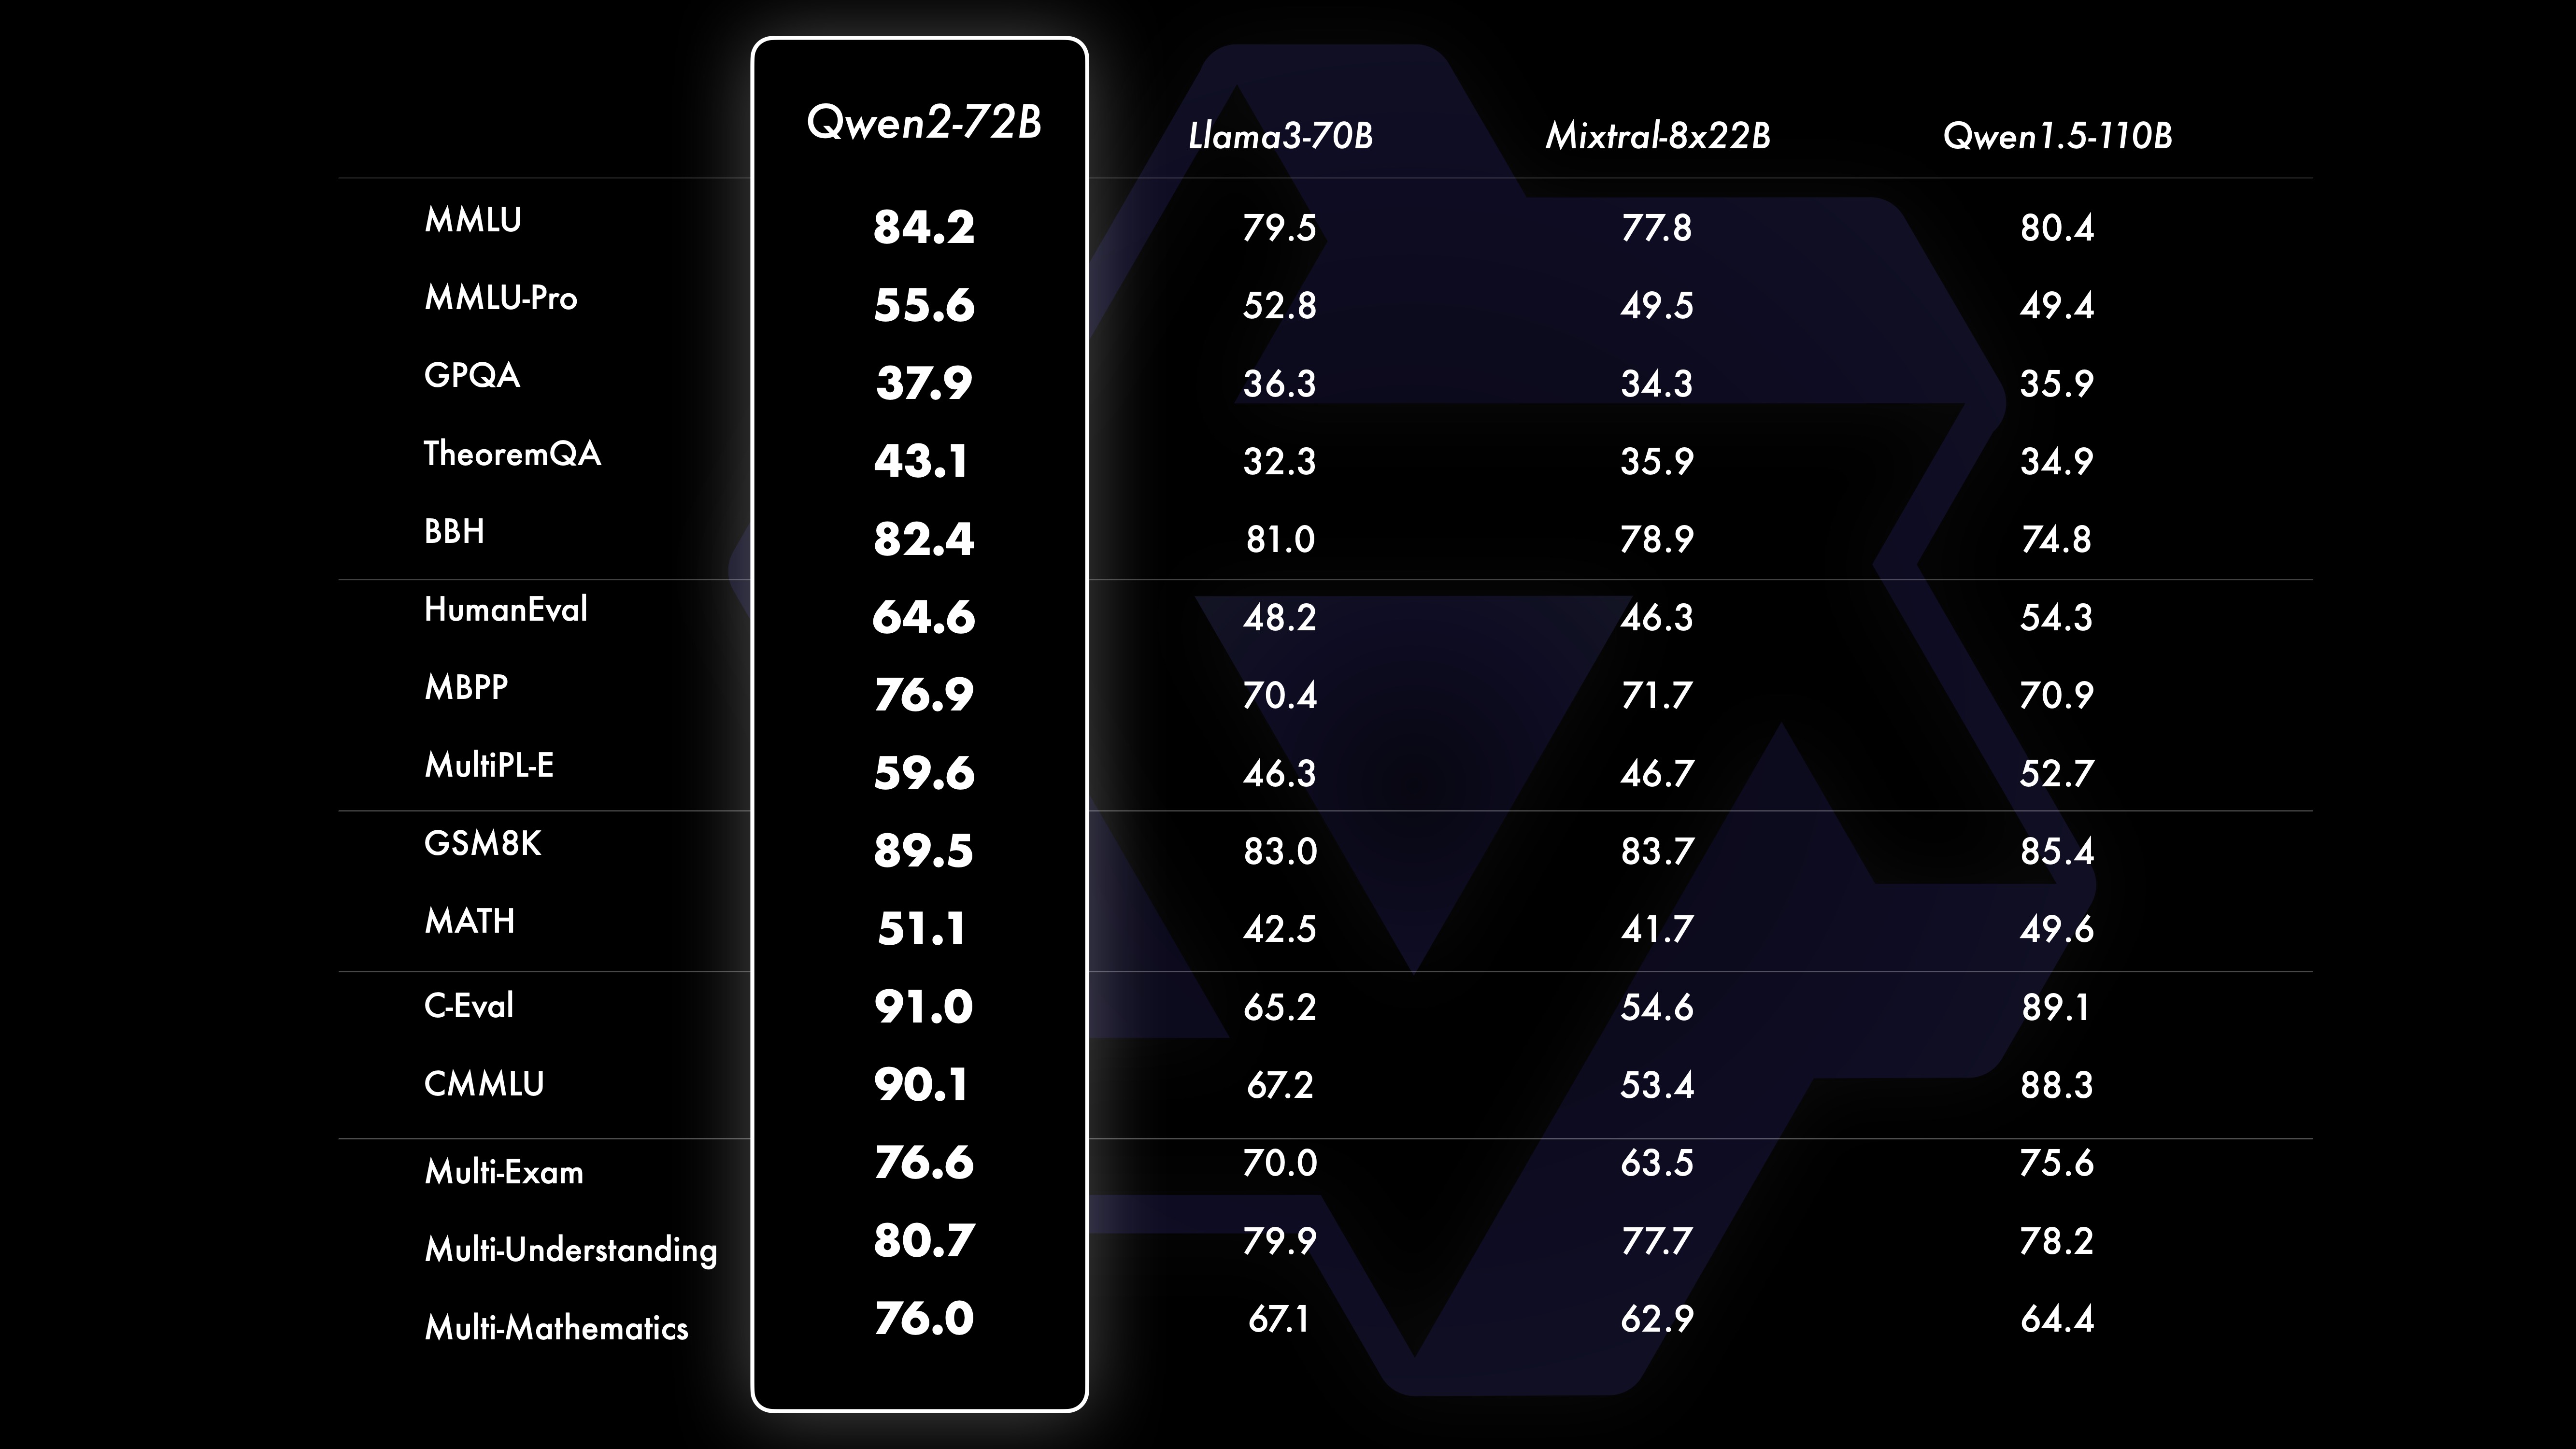
Comparative evaluations indicate that, relative to Qwen1.5, the performance of large models (70B+ parameters) has been significantly enhanced. The focus of our evaluation here is the large-size model Qwen2-72B. In terms of base language models, Qwen2-72B and state-of-the-art open models have been evaluated across different capabilities, including natural language understanding, knowledge acquisition, coding capabilities, mathematical skills, and multilingual abilities. Benefiting from a carefully curated dataset and optimized training methods, Qwen2-72B demonstrates superior performance compared to leading models such as Llama-3-70B. Notably, despite having fewer parameters, it outperforms its predecessor Qwen1.5-110B.
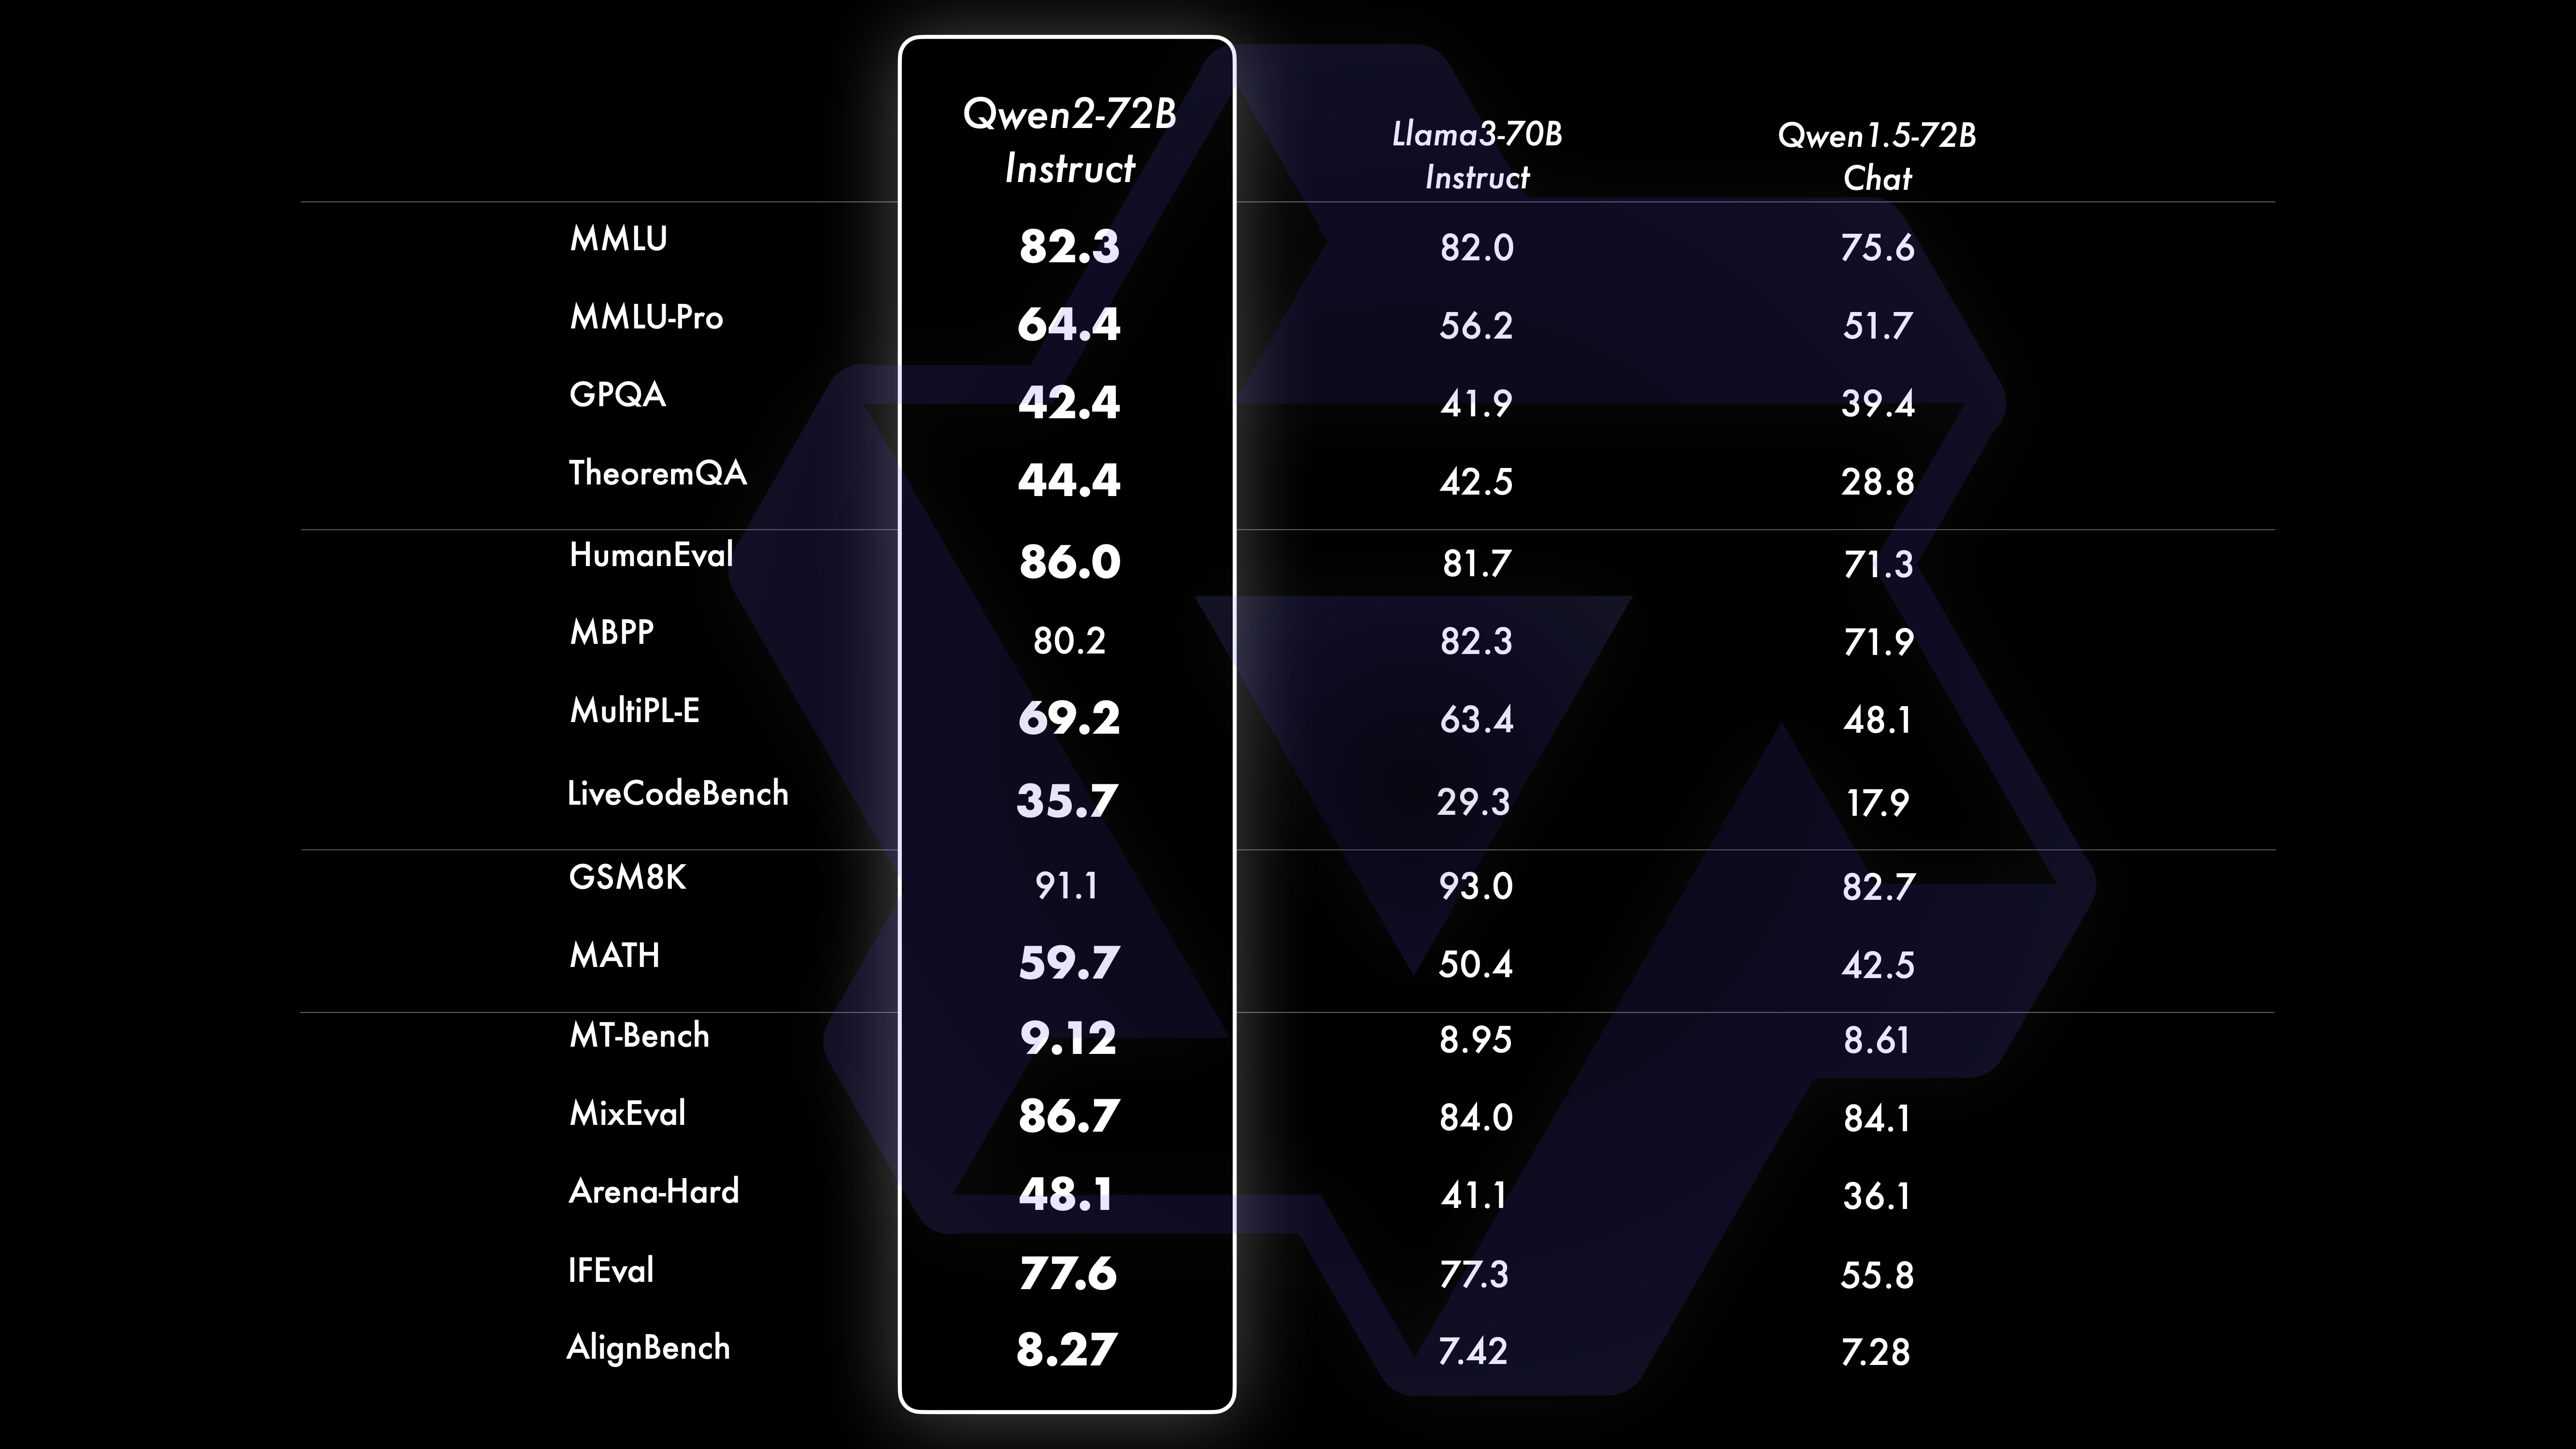
After extensive large-scale pre-training, we conduct post-training to further enhance the intelligence of Qwen and bring it closer to humans. This process further improves the model's capabilities in areas such as coding, mathematics, reasoning, instruction following, and multilingual understanding. In addition, it aligns the model's output with human values, ensuring it is helpful, honest, and harmless. The design of our post-training stage follows the principle of scalable training and requires minimal human annotation. Specifically, we study how to obtain high-quality, reliable, diverse, and creative demonstration and preference data through various automatic alignment strategies, such as rejection sampling for mathematics, execution feedback for coding and instruction following, back-translation for creative writing, and scalable supervision for role-playing. In terms of training, we employ a combination of supervised fine-tuning, reward model training, and online DPO training. We also adopt a novel online merging optimizer to minimize alignment tax. These collective efforts significantly improve the capabilities and intelligence of our models, as shown in the table below.
What's Next for Qwen2?
We are training larger Qwen2 models to further explore model scaling as well as our recent data scaling. In addition, we are extending the Qwen2 language model to multimodality, enabling it to understand visual and audio information. In the near future, we will continue to open-source new models and accelerate AI open-sourcing. Stay tuned!
Github: https://github.com/QwenLM/Qwen2
Download: https://modelscope.cn/organization/qwen
Experience: https://modelscope.cn/studios/opencompass/CompassArena/summary
Detailed Introduction: https://qwenlm.github.io/blog/qwen2/









