
 Script Planner Assistant▸
 AI Apps
 AI News
KEEP: Restore Faces in Low-Resolution Videos to High Definition
小编 ·

KEEP: Restore Faces in Low-Resolution Videos to High Definition
What is KEEP?
KEEP is a tool developed by a research team at Nanyang Technological University that can restore faces in low-resolution videos to high definition, making facial features more distinct. This technology has wide applications in fields such as video surveillance and film production, effectively improving the quality of facial images and providing clearer material for subsequent analysis and processing.
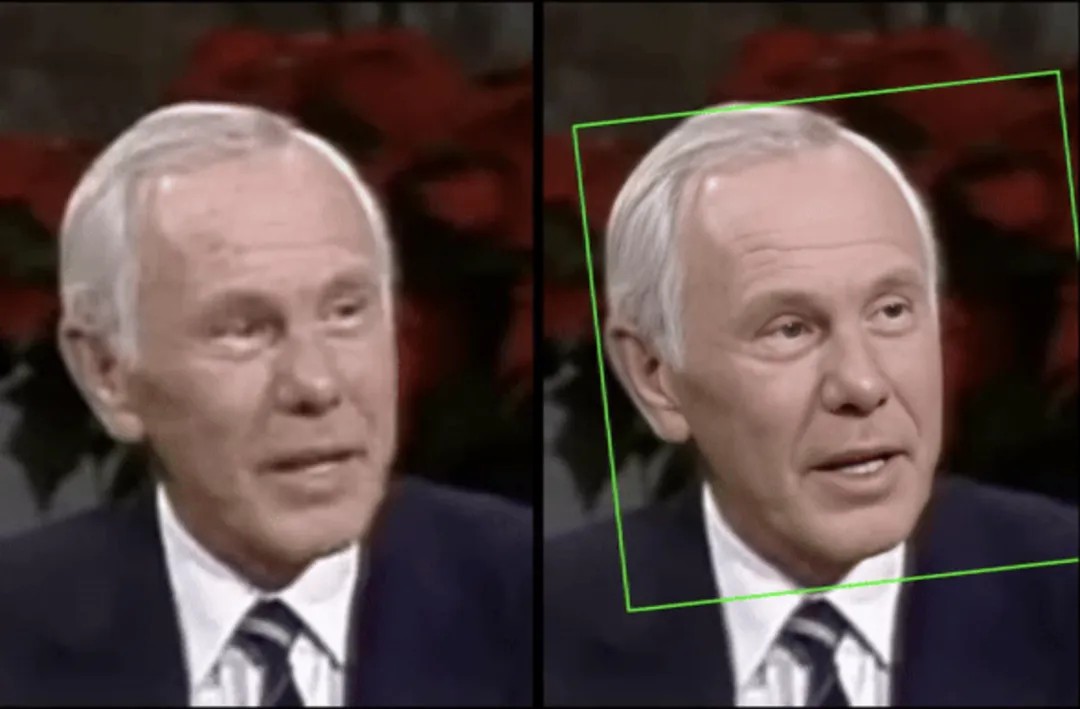
KEEP Core Technology
Kalman Filter Principle: By tracking facial features across video sequences and using the Kalman filter to predict facial features in the next frame, higher face super-resolution is achieved.
Feature Propagation and Dynamic Adjustment: Information obtained from previously restored frames is used to guide the restoration process of the current frame, reducing differences between consecutive frames.
Multi-Scale Processing: Combines multi-scale information to improve the detail representation and overall quality of facial images.
Cross-Frame Attention (CFA): Further enhances the correlation between different frames, helping maintain better timeliness and detail rendering during video playback.
KEEP Model Architecture
Encoder and Decoder: A model based on the Variational Quantum Generative Adversarial Network (VQGAN) is built to generate high-quality super-resolution images.
Kalman Filter Network: Combines the observation state of the current frame with the predicted state of the previous frame to form a more accurate estimate of the current state.
Cross-Frame Attention (CFA) Layer: Enhances the details of the current frame by matching and fusing similar features from the previous frame.
KEEP Advantages
Temporal Consistency: Maintains the coherence of faces in videos, avoiding temporal inconsistencies caused by processing each frame independently.
Detail Reconstruction: Effectively restores facial details such as eyes, nose, and mouth even in severely degraded videos.
Robustness: Performs well on non-frontal faces and severely degraded videos, stably estimating facial prior information.
KEEP Application Scenarios
Old Film Restoration: Enhances the clarity of faces in old films and restores details.
Video Surveillance Enhancement: Enhances face resolution in surveillance videos in the security monitoring field.
Social Media Videos: Improves face clarity in low-quality videos uploaded by users.
Video Conferencing Systems: Improves facial image quality during remote communication.
Virtual Reality (VR) Experience: Optimizes the rendering of character faces.
Project Link
https://github.com/jnjaby/KEEP









