
 Script Planner Assistant▸
 AI Apps
 AI News
Microsoft Launches Two New Models: Phi-4-Multimodal and Phi-4-Mini
小编 ·

Microsoft Launches Two New Models: Phi-4-Multimodal and Phi-4-Mini
Microsoft recently launched two new models, Phi-4-Multimodal and Phi-4-Mini.
Although these two models are designed to be relatively compact, their capabilities should not be underestimated. Phi-4-Multimodal is Microsoft's first multimodal model. It integrates capabilities such as speech, vision, and text processing, with a parameter count of 5.6 billion. Phi-4-Mini focuses on text tasks, with a parameter count of 3.8 billion. Both models place strong emphasis on optimizing performance on device-end and edge computing platforms, effectively reducing computational costs and latency.
Phi-4-Multimodal
What is Phi-4-Multimodal?
Phi-4-Multimodal is a multimodal model with 5.6 billion parameters, primarily responsible for handling text, vision, and speech/audio data. It employs an innovative technique called LoRA (Low-Rank Adaptation), combined with modality-specific routers, enabling it to effectively process and reason about data across multiple modalities without expanding the overall size of the model.
Technical Features
Phi-4-Multimodal uses the SigLIP-400M image encoder along with an MLP projector, allowing visual information to align with the text representation space. It also features a dynamic multi-crop strategy, enabling it to handle images of any resolution effectively. In speech-related tasks, although the LoRA components for the speech/audio modality are not large, it achieved a word error rate (WER) of 6.14% on the OpenASR leaderboard, ranking first, demonstrating outstanding performance in automatic speech recognition.
Functional Features
Multimodal Processing Capability: Phi-4-Multimodal is Microsoft's first multimodal language model with a unified architecture that integrates speech, vision, and text processing, with a parameter count of 5.6 billion. It can process various types of data, such as text, images, and speech, and fuse information from these different modalities to uncover correlations among them.
Speech Processing: In automatic speech recognition (ASR) and speech translation (ST), Phi-4-Multimodal surpasses professional speech models such as WhisperV3 and SeamlessM4T-v2-Large, delivering excellent performance.
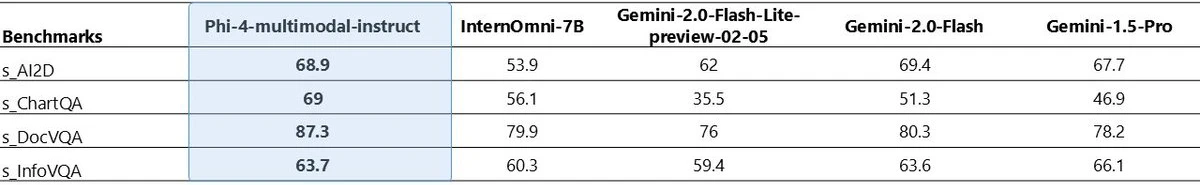
Vision Processing: In tasks such as document understanding, chart understanding, optical character recognition (OCR), and visual scientific reasoning, Phi-4-Multimodal is comparable to or even surpasses popular models such as Gemini-2-Flash-lite-preview and Claude-3.5-Sonnet.
Text Processing: Phi-4-Multimodal performs outstandingly in tasks such as text reasoning, mathematical computation, coding, instruction following, and function calling.
Application Areas
Phi-4-Multimodal not only performs well in vision and speech tasks but is also highly competitive in areas such as speech question answering, document understanding, optical character recognition, and scientific reasoning. However, in certain knowledge-intensive question answering tasks, it may perform slightly less well compared to larger-scale models.
Smart Assistant Domain: In smart home control, Phi-4-Multimodal can execute tasks more accurately based on the user's voice commands and images captured by indoor cameras.
Education Sector: For multimedia learning materials in online education, Phi-4-Multimodal can analyze images in videos and the text corresponding to explanatory audio, providing more comprehensive learning assistance for students.
Phi-4-Mini
What is Phi-4-Mini?
Phi-4-Mini is a highly efficient model specifically designed for text tasks, with 3.8 billion parameters. Its performance on language understanding and generation tasks is far better than what its parameter scale would suggest, and it is even comparable to larger models in certain aspects.
Technical Features
Phi-4-Mini adopts a 32-layer Transformer architecture, with a hidden state size of 3,072, and introduces the Group Query Attention (GQA) mechanism, enabling it to better handle long-context information. In addition, the use of fractional RoPE dimensions also allows for greater efficiency when processing long sequences.
Functional Features
Lightweight Design: The Phi-4-Mini model focuses on text tasks, with a parameter count of 3.8 billion. It employs the Grouped Query Attention mechanism (GQA) and input/output embedding tying techniques, optimizing resource utilization during long-context generation.
Efficient Text Processing: Phi-4-Mini performs excellently in tasks such as text reasoning, mathematical computation, coding, instruction following, and function calling, surpassing many popular large language models.
Application Scenarios
Mobile Applications: Within mobile apps, Phi-4-Mini can provide users with convenient language interaction services, quickly answering questions about tourist attraction information, local transportation, and more.
IoT Devices: For IoT devices such as smart speakers, Phi-4-Mini can perform simple voice interaction processing locally on the device, reducing reliance on the cloud, improving response speed, and protecting user privacy.
Performance
Although Phi-4-Mini is small in scale, it performs even better than comparable large models in tasks such as reasoning, mathematics, and coding, fully demonstrating its efficiency and accuracy on specific tasks.
Model Download:https://huggingface.co/collections/microsoft/phi-4-677e9380e514feb5577a40e4









